
Search results for tokens per second
AI & Enterprise
SiMa.ai unveils Palette 3.0 agentic software targeting physical AI
Physical AI company SiMa.ai unveiled Palette 3.0, a software update designed to support execution across physical AI models. The company said the update improves simultaneous multi-model performance to support AI inference and actions in real-world environments. It said Palette 3.0 can raise tokens-per-second throughput by up to 3.5 times in low-power settings. The update also adds open-source features and new capabilities including sensor fusion and digital twin simulation.
AI & Enterprise
China\'s MiniMax unveils M3.1 Flash, cuts AI agent costs 70 percent
China\'s AI company MiniMax has launched M3.1 Flash, a large language model designed to boost inference speed and sharply cut usage costs. The company said the model reduces AI agent task costs by 70 percent versus its predecessor and increases inference speed about threefold. Built on a mixture-of-experts architecture, it supports text, image and video inputs and up to 1 million tokens of context. MiniMax also disclosed pricing and availability across its API, subscription service and coding app.
AI & Enterprise
Cohere unveils North 2 enterprise AI agent platform with stronger orchestration, security and cost controls
Cohere unveiled North 2, a platform designed to run AI agents inside large organisations. The upgrade focuses on orchestration for multistep tasks and stronger controls over token spending. The company said enterprises often had to give up security, functionality or cost control when adopting AI agents, and it reflected large-scale operating experience across sectors including finance and the public sector. Administration tools also cover deployment and security settings.
-
AI & Enterprise
OpenAI launches $500-a-month Pro 500 plan, cuts existing Pro limits in half
-
AI & Enterprise
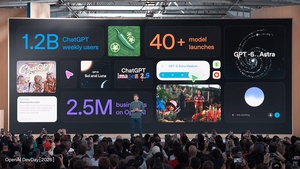
ChatGPT evolves into agent platform in OpenAI DevDay 2026 roundup
-
Industry
Qualcomm chip-based Microsoft Surface PCs show 80 percent faster local AI inference
-
AI & Enterprise
Nvidia begins mass production of Groq 3 LPX for AI agents
-
Industry
Nvidia unveils four new products ahead of earnings, focusing on token generation speed
-

AI & Enterprise
Small AI models near large-model performance as Dokpamo second evaluation nears
-

AI & Enterprise
Google, OpenAI race to ultrafast AI with Gemini 3.7 Flash and GPT-5.6 Sol Ultrafast
-

AI & Enterprise
OpenAI unveils \'Ultrafast\' mode to boost GPT 5.6 Sol speed
-

AI & Enterprise
Grok 4.5 tops speed and cost in AI coding tool test
-

AI & Enterprise
Cerebras compresses 163 seconds into 5 seconds, says GPU era is over
-

AI & Enterprise
Lightweight \'Needle\' model targets AI agents for low-cost smartphones
-

Telecommunications & Media
Apple silicon Macs could use external GPUs with Nvidia, AMD connectivity
-

Industry
MLPerf inference v6.0 benchmark released as AI inference datacentre chip race intensifies
-
AI & Enterprise
Cloud no longer needed? Ultra-large 400B-class LLM runs on iPhone in test
-
Industry
From GPUs to factory floors, Nvidia redefines manufacturing landscape