
Search results for MoE
AI & Enterprise
Krafton unveils 30B-class LLM \'Raon-1 Mini\' to boost cost efficiency
Krafton unveiled a preview version of its self-developed 30B-class large language model, Raon-1 Mini, on Oct. 21. The model supports Korean and English and was released on Hugging Face ahead of an official launch under an Apache 2.0 license. Krafton said the model uses a mixture-of-experts structure and its own linear attention technology to improve response speed and inference cost efficiency.
AI & Enterprise
China\'s MiniMax unveils M3.1 Flash, cuts AI agent costs 70 percent
China\'s AI company MiniMax has launched M3.1 Flash, a large language model designed to boost inference speed and sharply cut usage costs. The company said the model reduces AI agent task costs by 70 percent versus its predecessor and increases inference speed about threefold. Built on a mixture-of-experts architecture, it supports text, image and video inputs and up to 1 million tokens of context. MiniMax also disclosed pricing and availability across its API, subscription service and coding app.
AI & Enterprise
U.S. big tech targets open-weight AI models as Meta steps up offensive after Nvidia
U.S. big tech companies are moving into open-weight AI models long led by Chinese firms, putting the competitive landscape in focus. Meta unveiled its 816 billion-parameter Muse Spark Open model, describing it as the best U.S. open-weight model to date. The model supports up to 1 million tokens of context and takes text, images, video and audio as input. Meta outlined local deployment using two Mac Studio systems. Nvidia is also weighing further investment in or an acquisition of ReflectionAI, the Financial Times reported.
-
AI & Enterprise
Kakao unveils AI training optimisation and model lightweighting research at COLM 2026
-
AI & Enterprise
Upstage unveils 35 billion-parameter sLLM Solar Mini 4
-
Industry
Qualcomm maps AI future: smartphones stay, agents need partners, personalisation starts on the body
-
Industry
Snapdragon Summit 2026: Smartphones can run 30 billion-parameter AI models
-
Industry
Qualcomm fleshes out \'AI smartphone\' vision, up to 1 million tokens a day
-

Industry
Qualcomm boosts Hexagon NPU memory 50 percent, targets AI agents
-

AI & Enterprise
DeepSeek V4.1 Flash nears GPT-6 Astra performance at 1.4 percent of cost
-
Games & Commerce
Korean game makers unveil new titles at Tokyo Game Show 2026
-
Games & Commerce
Smilegate to demo two new titles at Tokyo Game Show 2026
-
AI & Enterprise
Naver Cloud to develop 700B cybersecurity AI model, preloads 4,000 GPUs
-
AI & Enterprise
SKT bets on \'intelligence improvement loop\' for AI-for-everyone push
-
AI & Enterprise
Rethinking AI performance scaling beyond parameter count
-
AI & Enterprise
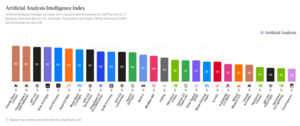
Motif\'s Motif 3 scores 47 on AAII, ranks 9th globally and 1st in South Korea
-
AI & Enterprise
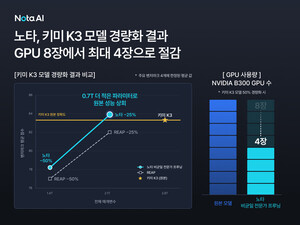
Nota lightens Moonshot AI\'s Kimi K3, cutting GPU needs by up to half
-
AI & Enterprise
Four teams in Korea\'s sovereign AI foundation model project ready for second review with different scale-up strategies