
AI audio company ElevenLabs said on Wednesday it launched its next-generation text-to-speech (TTS) model, Eleven v4, and a low-latency model, Eleven v4 Turbo.
Eleven v4 generates speech by reflecting a text's tone and speed, character traits and context. It allows users to adjust speaking style, emotion and sound effects using natural-language instructions or tags within sentences.
Supported languages expanded to more than 90 from 70 in the previous v3. It applies a new speaker identification method to keep each speaker's vocal characteristics even when generating speech multiple times, and is designed to create multi-party conversations by using earlier utterances as context.
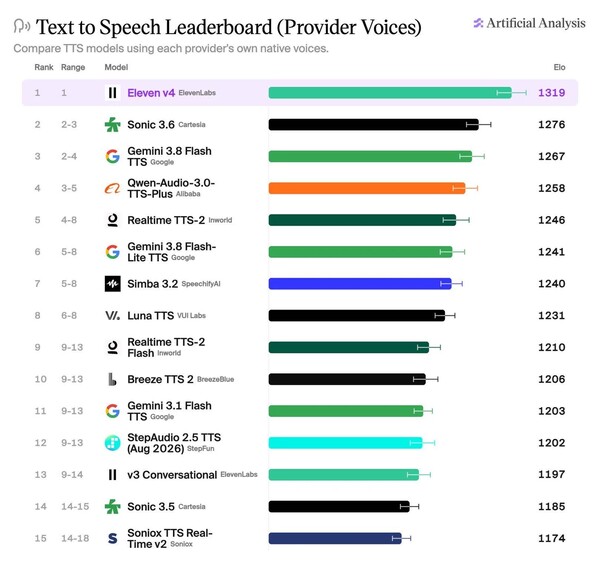
The company said Eleven v4 ranked first in the "Provider Voice Arena" evaluation conducted last September by AI model assessment organisation Artificial Analysis.
Eleven v4 Turbo, released alongside it, reduces latency for real-time voice AI agents. Intermediate inference latency during the first-response generation process averages 100 milliseconds, and it integrates with ElevenLabs' conversational agent platform, ElevenAgents.
Both models are available via ElevenCreative, ElevenAgents and ElevenAPI.
Mati Stanishevsky (마티 스타니셰프스키), ElevenLabs' co-founder and chief executive officer, said, "Based on broad emotional expression and contextual awareness, we made it usable in content creation and AI agents."
 Seulgi Son
sageson@d-today.co.kr