
TypeSafe AI, founded by former OpenAI staff, has released a new AI model called Jev that has quickly become a talking point in the AI field. Prominent figures appear to be offering a comment on Jev in passing.
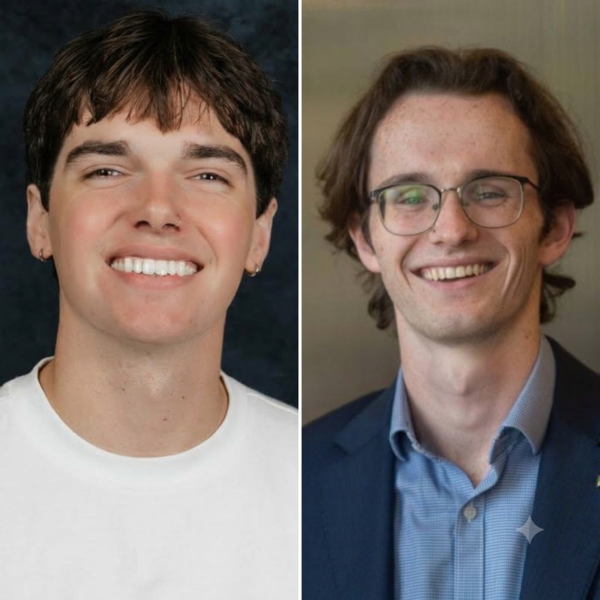
Daniel Shea (다니엘 셰이) and Seán Roche (션 로시) of LangChain, an AI application development framework company, released a post analysing Jev. The two focused on Jev’s potential from the perspective of evaluating AI agents.
Jev, which TypeSafe AI calls a System 1 model, is fundamentally different from existing large language models. It does not generate text. Rather than writing and holding conversations like ChatGPT, Jev is effectively an AI model that makes judgments in place of software.
For example, when a customer inquiry comes in, it judges the content, such as, “This is a refund issue.” A customer service system can take that result and automatically assign a ticket to the refund team. It also outputs responses in predefined forms such as “Send to refund team,” rather than long sentences. It is not an AI that writes well, but one that quickly makes the decisions needed in business processes. AI agents can hand simple judgments to Jev without calling an LLM each time.
So far there have been 2 broad ways to evaluate agents. One is code-based evaluation, and the other is an LLM-as-a-judge approach.
According to the authors, code-based evaluation is fast and cheap. But its scope is narrow. Even if it can check whether an agent called a tool, it is hard to judge whether it answered correctly. The limitation is more pronounced in tasks with multiple possible correct answers.
LLM judging can fill that gap. It reads the question, the action log and supporting materials all at once and makes a decision. But results can differ each time. It is also slow and costly.
The authors believe Jev can solve this problem in a different way. They said agent evaluation ultimately involves making a decision. It scores an agent by looking at its state and actions. Jev is optimised for this judgment task. General LLMs are different. They make judgments by generating words one by one.
To evaluate Jev, LangChain built a test agent using its agent framework Deep Agents. It created a dataset with 5 weather-related questions and had Jev, GPT-5.6 Luna, GPT-5.6 Terra and Claude Sonnet 4.6 each evaluate the same execution logs 100 times. It compared results using human-assigned scores as the correct answers.
The results were clear. According to the authors, Jev’s accuracy matched the human benchmark in all 500 judgments. Terra scored 99.8 percent, Luna 96.4 percent and Claude 80 percent.
Jev also had the smallest score variation. With an average deviation of 0.0000149, it was 433 times lower than Luna, 913 times lower than Terra and 92 times lower than Claude. The authors said, “This experiment alone cannot conclusively explain why the variation is small,” but added, “The model architecture trained to output typed, predefined answers may have had an influence.”
Cost and speed differences also warrant attention. Jev took an average 0.44 seconds and cost $0.00035 per case, while Claude cost a total of $28.17 for the same task. Jev’s cost was about $0.34.
The authors said, “Low cost makes it possible to conduct evaluations more often and more broadly,” adding, “For a production agent that accumulates 10,000 work logs a day, this kind of cost difference can change the operating approach itself.”
They rated Jev’s potential highly but also maintained a cautious stance. The authors stressed, “Low cost is not always good. An evaluator that is consistently wrong can pour out large volumes of incorrect feedback. Human review and checking whether the evaluation model aligns with human judgment are still necessary.” They also made clear that this was only one case and that it remains to be seen whether the same results will appear with other agents or in real operating environments.
Even so, they appear fairly positive about Jev’s potential. The authors said, “System 1-type models could make high-quality evaluation more widely available,” and added, “More execution logs will turn into feedback, problems will be found faster, and development will also speed up.”
 Chi-gyu Hwang
delight@d-today.co.kr