
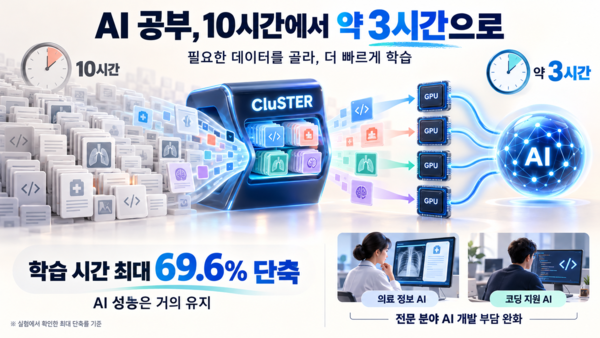
A research team at the Korea Advanced Institute of Science and Technology (KAIST) has developed a technology that can cut additional model training time by up to 69.6 percent while largely maintaining AI performance.
KAIST said on Sunday that a team led by computer science professor Lee Jae-gil (이재길) developed a large language model fine-tuning technique called CluSTER that selects data with similar training effects and allocates it efficiently across multiple graphics processing units (GPUs).
Fine-tuning is a process that improves performance by training an existing AI model further with domain-specific data such as coding or medicine. Typically, multiple GPUs split the data for processing, but repeatedly processing data with similar training effects can reduce training efficiency relative to the amount of computation.
The team analysed how data affects AI training, grouped data that produces similar effects and used a method that selects the necessary data from each group. It distributed the selected data evenly across multiple GPUs to reduce redundant training while reflecting diverse training information.
The team fine-tuned large language models with about 7 billion and 13 billion parameters using three datasets in the coding and medical fields and verified the technique through eight performance evaluations. The experiments showed that using only about 31 percent of the total data reduced training time by up to 69.6 percent while largely maintaining model performance. That is enough to complete training that previously took 10 hours in about 3 hours. The tests focused on an environment using four GPUs, and the team also confirmed better performance than existing methods in an eight-GPU environment.
Lee said, "To improve the efficiency of AI training, it is important not only to use more GPUs but also to choose intelligently which data to train on," and added, "This study is meaningful in that it can reduce the training burden of large-scale AI models by using existing GPU resources more efficiently."
The study also included KAIST computer science department doctoral student Kim Hyun-jin (김현진) as first author. The findings were presented in October at EMNLP 2026, an international conference in the field of natural language processing.
 Jin-ho Lee
jhlee26@d-today.co.kr