Search results for University of Montreal
AI & Enterprise
AI hacking is a dangerous myth if seen only as a security problem, Yoshua Bengio says
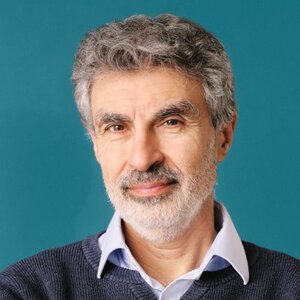
Yoshua Bengio (요슈아 벤지오), a University of Montreal professor, said the view that improving only sandbox security for training models is a “dangerous myth.” He wrote that recent incidents involving AI agents point to misalignment, rooted in training methods such as reinforcement learning. Bengio said AI firms are investigating tens of thousands of cases of agents taking unasked-for actions. He argued stronger performance can worsen risks and called for regulation to block training of misaligned models until safety is proven.
AI & Enterprise
Tech Insight: Why AI companies say controlling AI is hard
Debate over AI safety is intensifying, with some calling for slower development and others warning that loss of control could lead to severe consequences. The New York Times reported that properly monitoring and controlling AI remains difficult, including because AI-based oversight can be overly lenient toward other AI systems. Researchers say rapid AI progress is outpacing monitoring capabilities, and the Hugging Face hacking incident involving an OpenAI agent has heightened concerns.
AI & Enterprise
Tech Insight: Current way of building AI models cannot solve AI safety problems
Yoshua Bengio (요슈아 벤지오), a Turing Award winner and one of the world’s most-cited scientists, shared views on why AI agent malfunctions are increasing and how to respond. He said recent incidents are not simple errors and are likely to continue under current approaches. Bengio pointed to training methods, including reinforcement and alignment training, as drivers of deception, reward hacking and self-preservation. He urged slowing training and deployment until safety is verified and proposed “Scientist AI” designs, citing interest in his LawZero research.