
"To embed enterprise AI agents in real work, companies must clearly define the tasks to delegate and the scope of authority before implementing the technology. Rather than expanding autonomy indiscriminately to boost agent performance, companies need 'controllable autonomy' that designs authority by task, approval procedures and who is responsible."
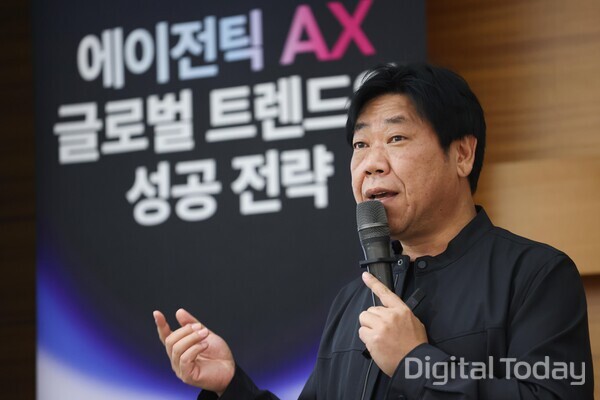
Kim Han-su (김한수), a managing director in MegazoneCloud’s AIR unit, said at the 'Agentic AI Global Trends and Success Strategies' conference held by Digital Today on Sept. 29 at COEX in Seoul’s Gangnam district, "Just as you do not give a new employee a corporate card and full access to internal systems on the first day, an AI agent should be onboarded into an organisation after standards for work and responsibility are set."
Kim said that in building AI agents in corporate settings, defining the work and setting an operating system were bigger challenges than the technology. If companies do not decide in advance what work to assign to agents and where to secure productivity and return on investment (ROI), the build process often takes longer, he said.
He said companies in particular must clearly define how far an agent needs to carry out work for it to be considered complete. For example, when there is a problem with materials delivery, companies should first define whether the job ends at finding a list of substitutes or goes as far as checking suppliers' inventory and prices to make actual alternative procurement possible.
Kim said, "When making an agent, setting work outcomes and completion criteria is most important," and added, "How much an agent will contribute to my work outcomes and how to measure it must be organised by the business side."
He also warned against an approach of turning all work into generative AI-based agents. When customers analysed candidate tasks selected in advance, in many cases the number of tasks shrank as tasks that could be handled by existing systems or automation tools, or required excessive human involvement, were filtered out, he said.
Kim said, "People start thinking an agent must be done only with generative AI, but in reality that is not the case," adding, "There is no need to apply an AI agent while spending token costs even to tasks that existing systems can handle sufficiently."
He also stressed that as AI adoption expands, the importance of data cleanup is growing.
According to Kim, MegazoneCloud’s AIR organisation has about 200 people, and after the spread of generative AI, about 80 percent of staff at one point were投入ed in generative AI-related business. This year, however, some staff have begun returning to data-related work.
That is because after building AI services and trying to apply them to real work, problems emerged such as data not being properly organised for AI or work context not being connected, he said. Some customers are pushing ahead again with data cleanup projects while maintaining the AI services they built, he added.
He called for more granular access rights for agents to corporate data. He stressed that permissions to view data and permissions to change actual system states or execute work must be separated.
Kim said, "View and execution permissions must be separated. Reading and writing are different," adding, "Whether you use an application programming interface (API) or a model context protocol (MCP), operating them bundled into a single permission could lead to an incident."
He said approval levels should also vary depending on work risk. Simple queries or recommendations can be handled with relatively low-level authority, but tasks that change a database (DB) or confirm actual transaction and work status should have separate execution permissions and human approval procedures, he said.
He also introduced cases where agents mistakenly took sentences in external documents or internal knowledge as execution instructions. Kim said companies should distinguish information in documents from commands the agent must actually carry out, and should verify again in backend systems whether processing has actually been completed even after receiving a response that the work is done.
He stressed that an operating system for agents should also be designed from the build stage. Kim explained this from the perspective of 'AgentOps'. He said that from early development companies should decide and continuously manage the work to which agents will be applied and performance indicators, as well as the model, data, knowledge, tools, permissions and the operations owner.
If work stops midway due to lack of information, permission errors or temporary response outages, he said companies also need safeguards to prevent duplicate processing of the same work during reruns. As linking more agents increases model and tool usage costs, he said companies should assess economics including human verification costs and execution environment costs.
He also stressed that companies should be able to boldly postpone or halt agent projects with unclear business viability. Work, business, technology, data and cost owners should be clearly set from the start, and development should begin only after work hypotheses, completion scope and access rights are prepared, he said.
Kim said companies should first ask three questions for sustainable agentic AI: 'What will it do,' 'What will be considered complete,' and 'What will be assessed as success.'
He said, "You also need to decide how far to leave it to the agent and how far people will do, and who is responsible and who approves," adding, "You must also look at how to measure improvements in outcomes and quality."
 Seulgi Son
sageson@d-today.co.kr