
[Digital Today reporter Chi-gyu Hwang (황치규)] Global AI audio company ElevenLabs said on Wednesday it has unveiled its speech-to-text models Scribe v3 and Scribe v3 Live.
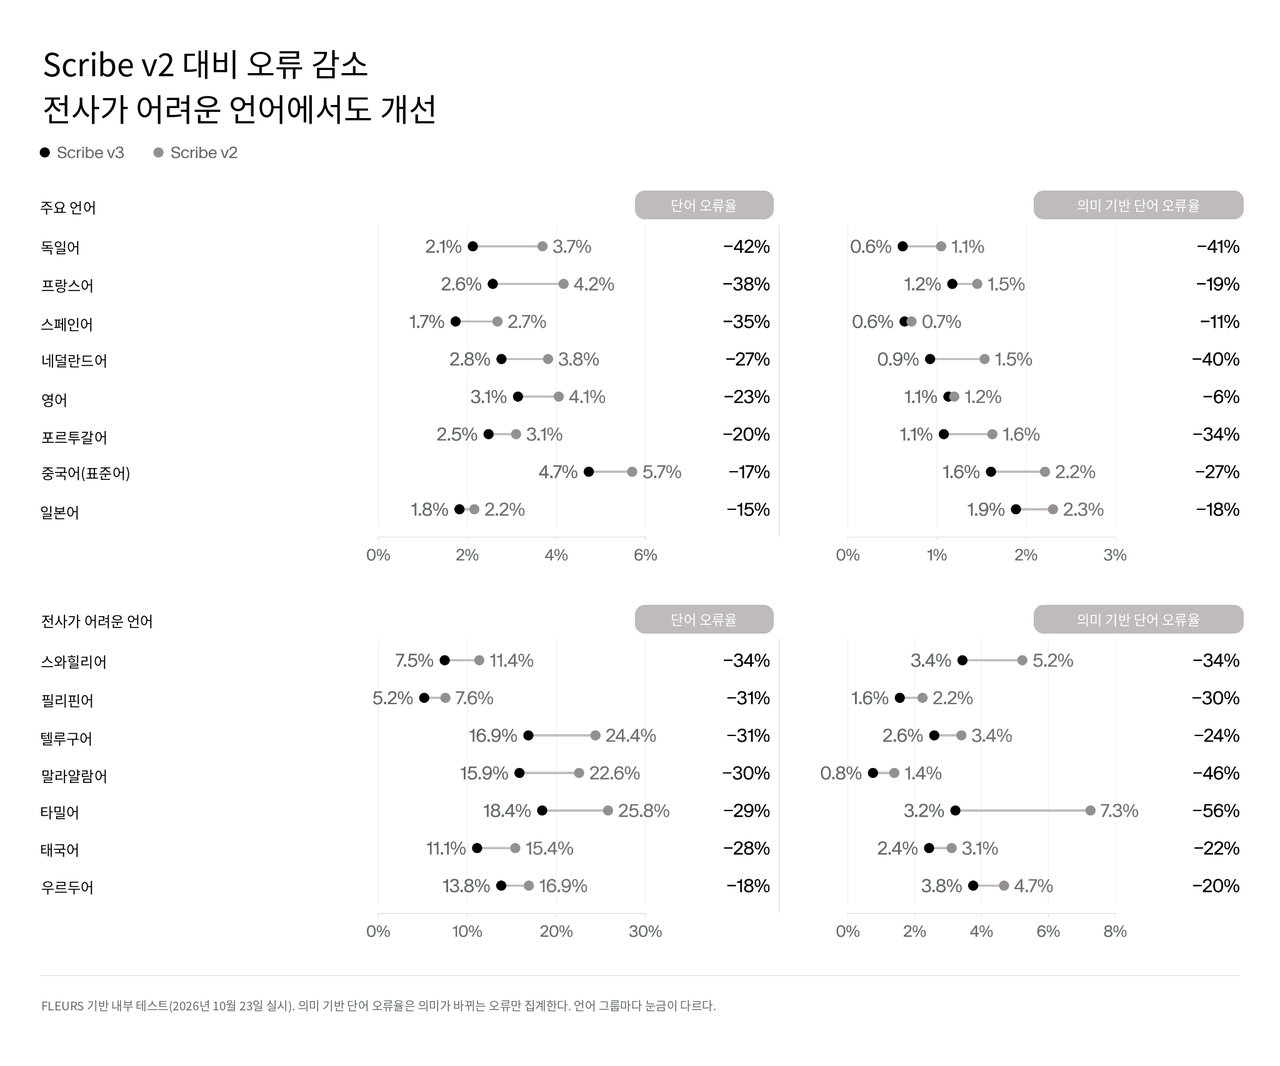
The company said Scribe is for recorded audio and reduced word errors by 27 percent compared with its previous model, Scribe v2.
In speaker diarization, which distinguishes who spoke, it recorded the lowest error rate among models ElevenLabs has evaluated in-house.
Scribe v3 Live is for real-time audio and reduced errors by 43 percent compared with the previous model, Scribe v2 Realtime. It supports speaker diarization, and turn detection performance has also improved, the company said.
About the Author
 Chi-gyu Hwang
delight@d-today.co.kr
Keyword
#ElevenLabs #Scribe v3 #Scribe v3 Live #Scribe v2 #Speech to Text
