
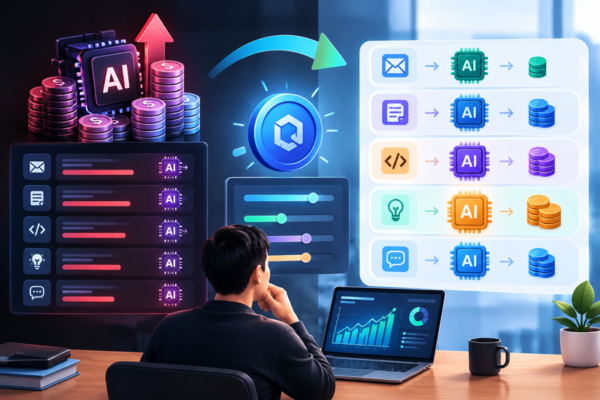
Many companies and users apply top-tier artificial intelligence models across the board even for simple tasks such as drafting emails or writing summaries, even though the highest-end models can cost up to 100 times more per token than smaller models. Token consumption is surging as use of AI agents and automation tools grows, making task-by-task model selection and usage controls a key challenge in managing corporate AI costs.
Decrypt, a blockchain media outlet, reported on Oct. 17 that Meta employees used a total of 60 trillion AI tokens over 30 days earlier this year. That followed an overheated internal competition over usage rankings. Tech columnist Gergely Orosz estimated the total at about $900 million based on Anthropic's list prices. The figure is a list-price estimate, and the amount Meta actually paid may have been lower.
An AI usage race has also appeared at other big tech companies. Meta, Amazon and Uber were reported to have operated internal leaderboards comparing employee use of AI tools. Uber was said to have exhausted its 2026 AI tools budget in about 4 months.
Nvidia CEO Jensen Huang has also urged wider AI use. He said on the "All-In" podcast in March, "If an engineer who makes $500,000 a year is not using at least $250,000 worth of tokens, I would be very concerned." The analysis is that encouraging AI use to boost productivity is feeding the usage competition and adding pressure to cost management.
A key issue is that price gaps between AI models are large. The highest-end models from Anthropic and OpenAI can cost up to 100 times more per token than the smallest models. OpenAI, for example, has models priced at $10 per 1 million input tokens and others at $0.10.
A token is the basic unit an AI uses to process and generate text. Tokens are used not only for the questions and context entered into a model but also for the answers the AI generates. In subscription products priced around $20 a month, the pace of token use affects usage limits. For companies connecting to AI through application programming interfaces, higher use directly raises bills.
Zhuo Wang of consulting firm Bain & Company pointed out that companies often use the highest-end models even for tasks that do not require complex reasoning, such as writing emails. It is akin to applying Anthropic's high-performance Opus model to virtually every task.
A similar issue arose inside Amazon. Some employees were reported to have inflated usage by using internal AI tools for tasks with low relevance to their work. A senior vice president warned employees not to use AI for the sake of using AI. Treating usage itself like a performance metric can raise costs without improving productivity.
Another factor driving up costs is AI agents and orchestration. AI agents perform tasks through multiple steps such as searching, executing code and reviewing results. Token consumption rises if prior conversations and task context are repeatedly passed along in the process. Orchestration that splits work among multiple sub-agents can further increase call counts and context processing volumes.
Anthropic says that when a team-based agent in Claude Code operates in plan mode, it can use about 7 times more tokens than a normal session. The more autonomously an agent handles complex work, the more token consumption can rise in the background even if user input is limited.
A first way to cut costs is to separate model use by task difficulty. That means assigning emails, copyediting and simple summaries to smaller models, and applying top-tier models only to tasks that require high accuracy, such as complex reasoning or important decision-making.
Companies can also compare results by assigning each of the five most recent tasks to a high-performance model and a smaller model, then keep using the smaller model if it meets requirements. The outlet introduced this model-routing strategy as a way to cut API costs by up to 99 percent. Actual savings can vary by task type, model pricing and usage volume.
Managing prompts and context also matters. Specifying required items and output formats from the start, rather than repeatedly revising questions to refine an answer, can reduce unnecessary follow-up prompts. Starting a new conversation when the topic changes can also help avoid repeatedly passing along prior context.
Anthropic describes the accumulation of low-relevance information over long conversations and the resulting decline in answer quality as "context rot." As context grows longer, it not only increases the number of tokens that must be processed but can also make it harder to focus on key information.
Limiting answer length can also deliver direct cost savings. For Anthropic and OpenAI top-tier models, output tokens cost 5 times more than input tokens. Adding instructions such as "Answer within 100 words" or "Output only the revised parts" can reduce unnecessarily long outputs.
There is also no need to leave calculations and aggregation entirely to AI. Instead of inputting a long table in full for analysis, it may be more efficient to have the model write the required formulas or a short script, run it directly, and then feed only the calculation results back into the AI. That reduces token use by doing repetitive calculations with standard tools rather than through a model's reasoning process.
In development environments, caching and batch processing are also cited as cost-cutting measures. Caching repeatedly used system instructions and fixed context can reduce the cost of re-entering the same content each time. OpenAI and Anthropic offer a 50 percent discount for batch jobs, which can be used for large workloads that do not require real-time responses.
For example, bundling 1,000 invoices into a batch job rather than processing each one in real time can lower call costs. Still, companies need to check support conditions and which job types can be applied to caching and batch processing.
Execution steps and spending limits should also be set for AI agents. Defining completion conditions clearly before starting work, and setting maximum execution steps and a dollar-denominated budget, can prevent an agent from repeating unnecessary work to refine results. Shopify was reported to operate a mechanism that immediately blocks developer access if spending surges sharply in a day.
Token prices are falling, but total spending is rising. Silicon Data's token spending index shows token prices have fallen more than 90 percent since 2023, but spending related to large language models has doubled since late 2025. Bain & Company analysed that while token costs fell by half between December 2024 and 2025, usage rose 450 percent.
This shows that falling unit prices for AI models do not necessarily lead to lower overall costs. If usage rises faster as prices fall, total corporate spending can increase instead.
Ultimately, cutting AI costs requires more than choosing cheaper models. Companies need an operating system that assigns suitable models by task, manages prompts and context efficiently, and controls repeated agent execution and spending. As competition to adopt AI shifts from expanding usage to improving real productivity, corporate priorities are changing from how much they use to how efficiently they use it.
 Jinju Hong
hongjj@d-today.co.kr